Submissions for Open Source Higgsfield close Nov 3, 9:00 AM PT. LSDub is our entry in the Open Weights, Most Innovative and LTX categories.
Match the lip-sync to the audio, without re-rendering the whole shot.
Built for music videos. Spoken dialogue, film dubbing and other uses are still in development.
Photoreal lip-sync dubbing that warps the face's own mouth (its teeth, gums, lips and tongue) to say new words. No painted mouth. No face swap. Open weights only. Every pixel on screen is the clip's own, moved to fit the audio frame by frame.
Our entry in the Open Source Higgsfield ComfyUI contest.
The two-minute tour: how LSDub re-syncs a singer without re-rendering the shot, and how it scores every shot. The teeth, the gums, the tongue: all harvested from the face itself, then warped to the new vocal.
Every other lip-sync tool paints a new mouth over the face or swaps the face outright. LSDub does neither. We harvest the clip's own mouth, build it in a canonical dental-arch atlas, and warp that atlas to the audio target for every frame. The result is the person's real teeth and lips — never a model's guess.
Teeth, gums, tongue and lips are the face's own, lifted from its best frames and re-posed. No inpainting, no painted enamel, no borrowed smile.
Built on LTX-2.5 and open-weights tooling only. No partner APIs, no closed models — qualifies for Open Weights Only + the LTX bonus.
One vocal track drives a whole gallery of faces. The same words, the same timing, across every character — a face-chain you play.
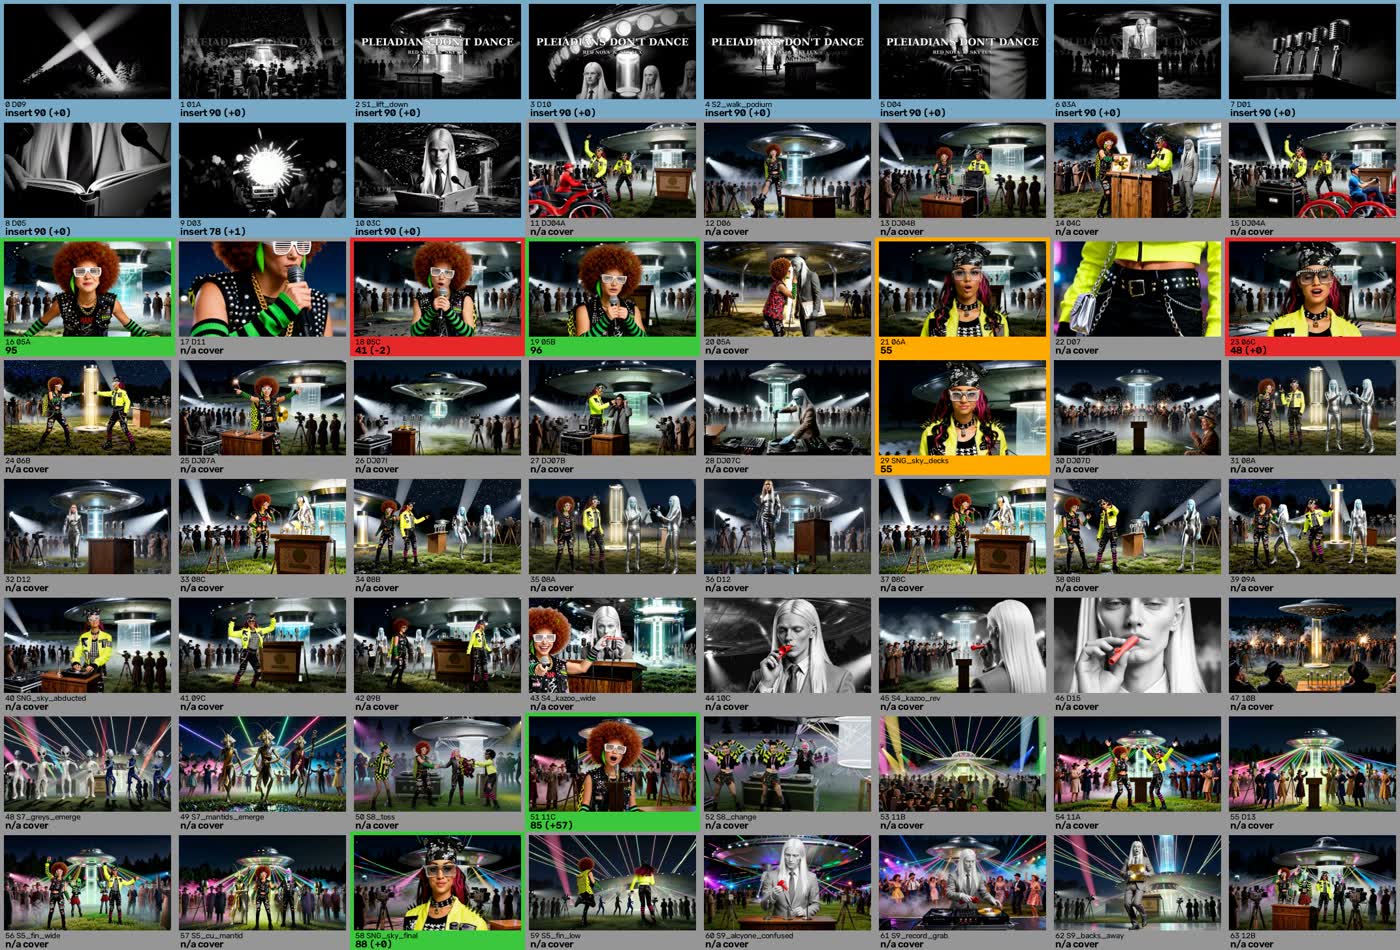
A music video isn't one face. It's sixty cuts, two singers, wides, inserts and a mic in the way. LSDub runs the whole cut, shot by shot.
--auto also renders the native warp and keeps whichever syncs better.The face's size in the delivered frame decides what LSDub does with it. The lines are parameters.
Hooks belong here. The singer is cropped to 512 px anyway, which zooms close-ups about 1.9–2.8×, and gets the full deep dive: shot kit, teeth atlas, 2× fps snap and closure press.
For verses. The face is tracked, cropped, upscaled, warped and scaled back down. Only the lower face is pasted, and on track gaps the source passes through untouched.
Too small to dub, so this tier is for held notes. The grammar gate flags any sung attack that falls on a wide so you can recut it. LSDub won't fake a mouth it can't read.
LSDub has a number of checkpoints for ensuring improved results. The QA suite of tools enables video, shot, audio and sync analysis.
--compare diffs it against the last cut.The scorecard sorts each cut into a class first, so you aren't blamed for editorial choices. Only real performance shots get a sync score.
A sung shot with the singer at medium or closer and the mouth visible at least 50% of the time. Scored 0–100: PASS from 75, REVIEW from 55, FAIL below 55. A mouth that barely moves is capped at 55.
Sung, but there's no readable singer: no face, a face that's too small, or a hidden mouth. It shows as grey n/a with the reason. It's an editorial note, not a lip-sync defect.
An unsung shot. Only motion, pops and sharpness are checked, and the score is capped at 90 so an insert never outranks a verified sung shot.
Reasons follow a fixed priority: no singer on screen → singer too small → mouth hidden → sync. A shot is never blamed for sync when the real cause is coverage.
64 cuts, split into 8 PERF, 45 COVERAGE and 11 INSERT. Fixing continuity took cut 19's measured sync correlation from 0.14 back up to 0.97.
The node pack, the four example workflows and the demo pack are on GitHub (Apache-2.0).
Every model in the pipeline is open-weights, and there are no partner APIs or closed endpoints. You can run all of it on your own box.
Scan, paint and the QA suite run on any machine. Inside ComfyUI the heavier checks use the GPU automatically when one is free, and hand it back for the render.
LSDub ships as a ComfyUI node pack, beginning with the vocal stage: split the stem, then isolate the lead vocal that drives the mouth. It runs locally through ComfyUI's own API and the Comfy SDK, on your own ComfyUI and your own weights. No cloud required.
Pick a face, give it words, hear it sing. One render opens every 15 minutes — you'll take a numbered place in line and the clip comes back to you.
Built with LTX-2.5. Open weights only. Every mouth is the face's own. #OpenSourceHiggsfield